SQL
SQL jobs are designed for structured data processing, analytical queries, and scheduled transformations. SQL jobs allow users to execute SQL queries directly against the Yeedu compute engine.
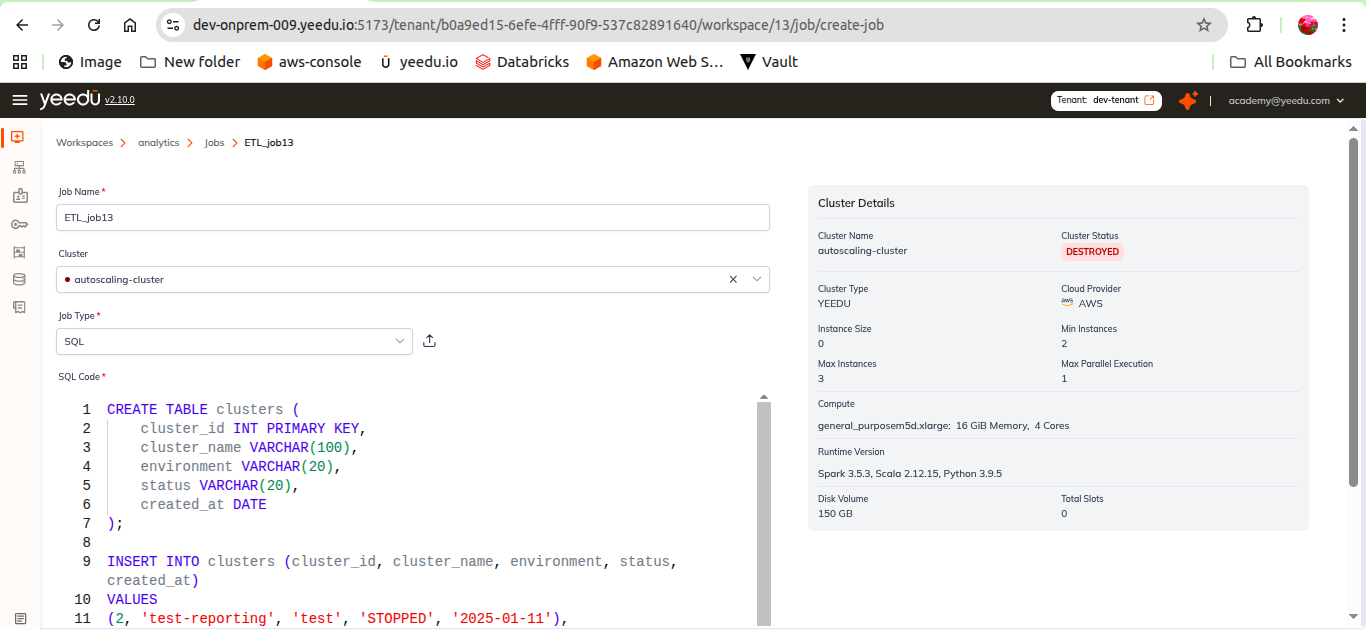
Input Methods
- Inline Query: Write SQL directly in the editor
- Upload SQL File: Upload
.sqlscripts with one or more queries
Required Fields
- Cluster: Cluster that will execute the SQL queries
- Path (Optional): Select a stored SQL script from the repository
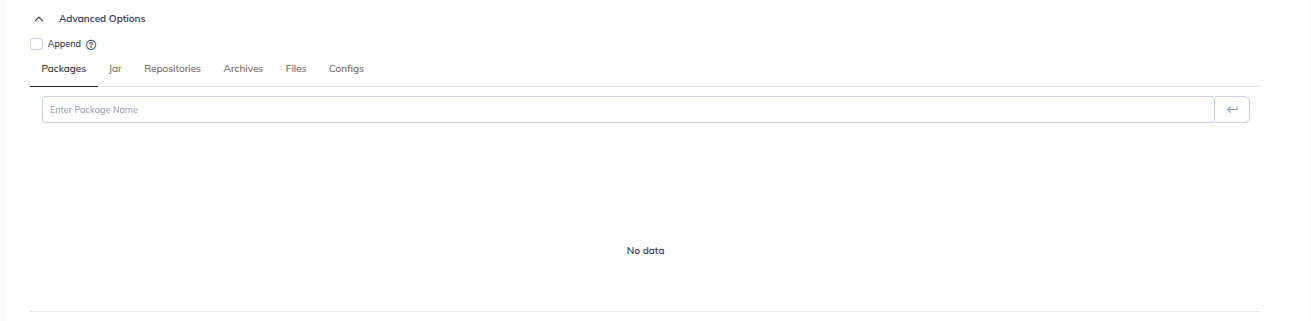
Advanced Options
You can configure:
- Packages – Add required dependencies
- Files – Include supporting files
- JARs – Attach external libraries
- Spark Configs – Configure Spark properties
- Concurrent Runs – Control parallel job executions
Common Use Cases
- Reporting pipelines
- Data quality checks
- Incremental transformation jobs