JAR Job
A JAR job is best suited for production-grade workloads that require compiled code, well-structured Spark logic, and reusable applications. It enables efficient execution of complex data processing tasks using pre-built artifacts.
JAR jobs allow you to execute Java or Scala-based Spark applications packaged as a .jar file.
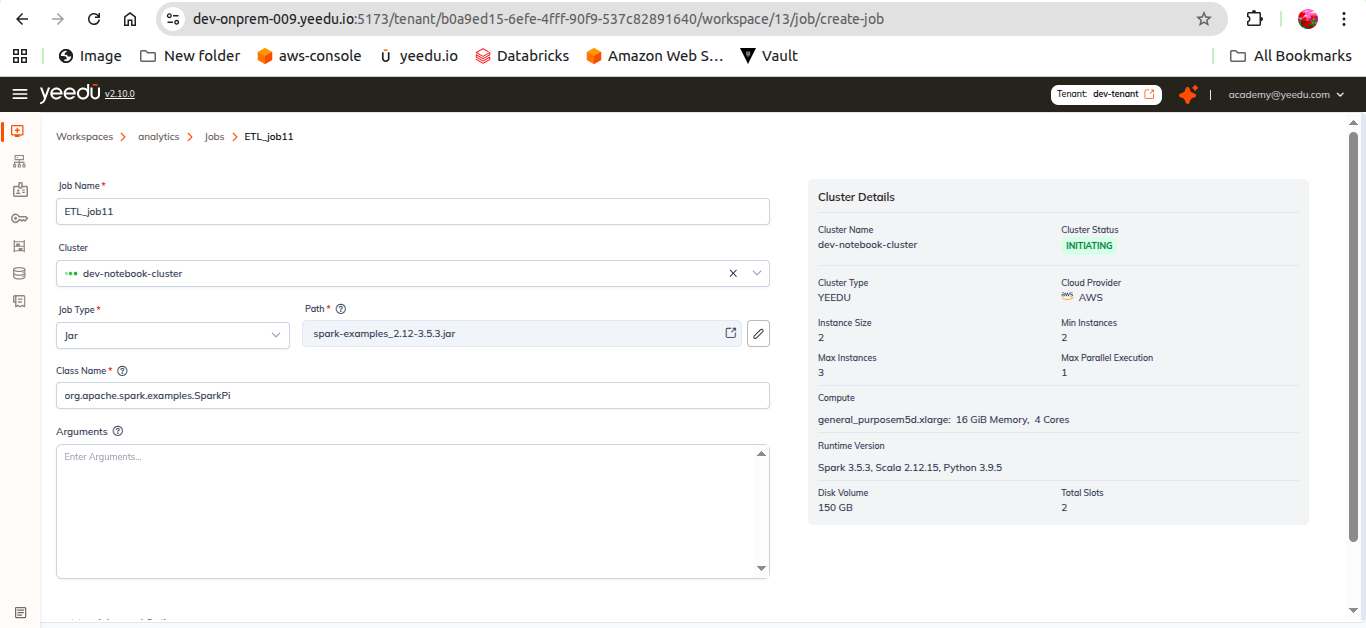
Required Fields
- Class Name: Fully qualified class containing the
mainmethod - Arguments: Space-separated arguments passed to the application
- Cluster: Target cluster where the job runs
- Path: Location of the JAR file in the repository
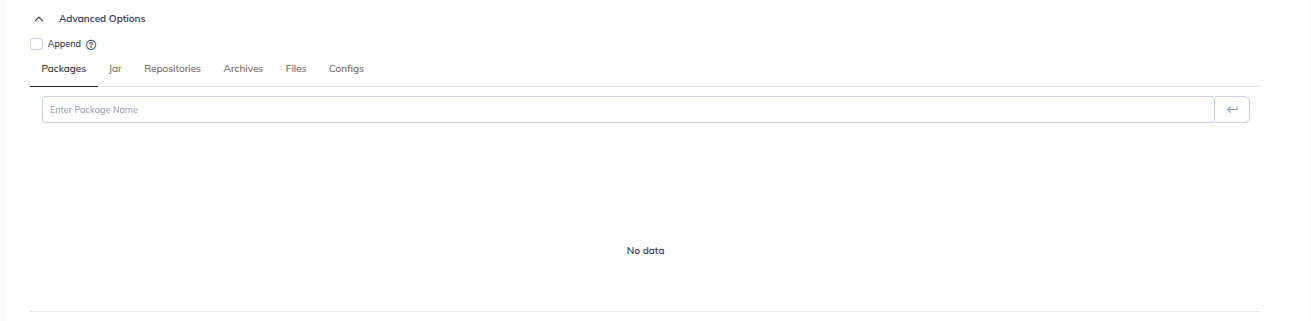
Advanced Options
You can further customize your job configuration using the following options:
- Additional JARs – Include extra dependencies required for execution
- Repositories – Specify custom repositories for dependency resolution
- Spark Configs – Define Spark configuration properties
- Driver Configs – Configure driver-level settings
- Archives – Add archive files needed during execution
- Files – Attach additional files required by the job
- Packages – Include external libraries or packages
When to Use JAR Jobs
Use JAR jobs in the following scenarios:
- Performance-critical workloads
- Stable and versioned data pipelines
- CI/CD-driven Spark applications